Bengali, spoken by over 230 million people, remains severely under-resourced in spoken language research. Existing open Bengali ASR corpora are largely confined to short, read or crowd-sourced speech and lack speaker diarization and long-form audio. Lipi-Ghor addresses this gap with a large-scale weakly supervised Bengali speech corpus built from public YouTube content.
The released corpus contains 885.34 hours across 998 unique videos from 596 channels and spans 17 diverse domains. Each recording is represented in SSTT format—Speaker, Speech, Transcription and Timestamp—by aligning automated diarization with Bengali caption tracks. A separate 500-clip, human-corrected gold split supports reliable evaluation, while the accompanying construction pipeline is designed to transfer to other caption-rich, low-resource languages.
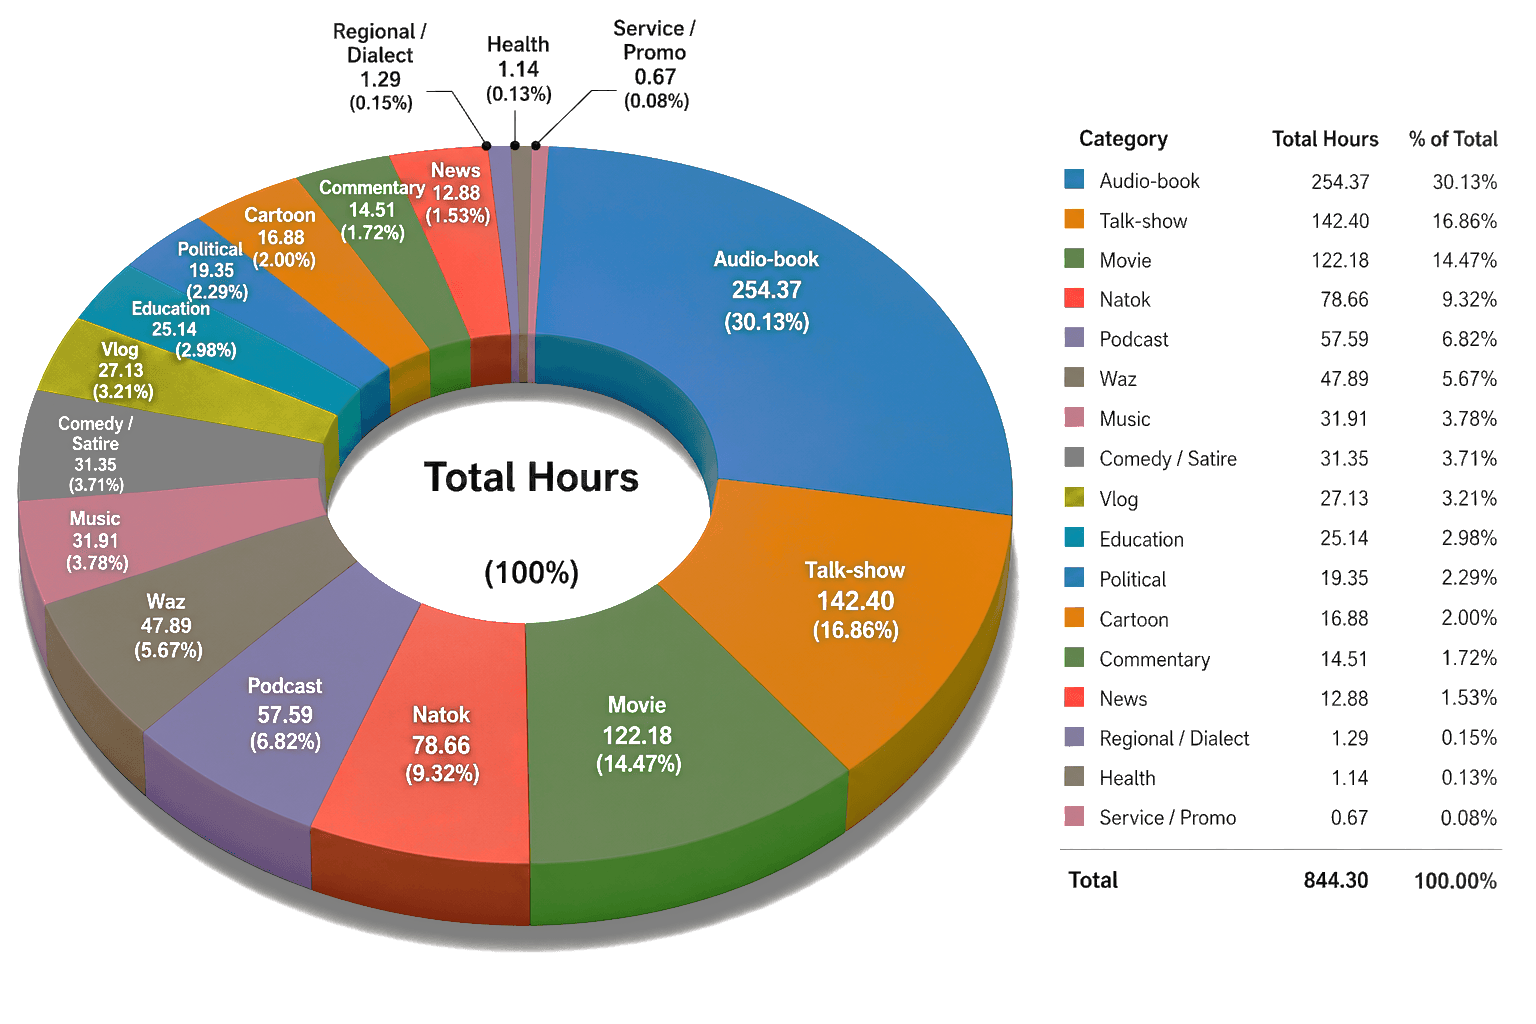
885.34 hours of Bengali speech across 17 domains, including audiobooks, talkshows, movies, natok, sermons, news, cartoons and regional speech.
Speaker turns are aligned with speech, Bengali transcription and timestamps so downstream work can operate beyond plain utterance-level ASR.
A four-stage recipe combines domain-aware curation, caption filtering, extraction and diarization for scalable corpus building.
The construction pipeline is deliberately simple: identify caption-rich Bengali channels, retain videos with Bengali caption tracks, extract audio and subtitles, then align diarized speaker turns with transcript segments into SSTT records.
Domain-aware manual discovery of Bengali YouTube channels.
Keep videos with native Bengali bn caption tracks.
Extract audio and subtitles, then deduplicate across domains.
Precision-2 diarization aligned with Bengali transcripts.
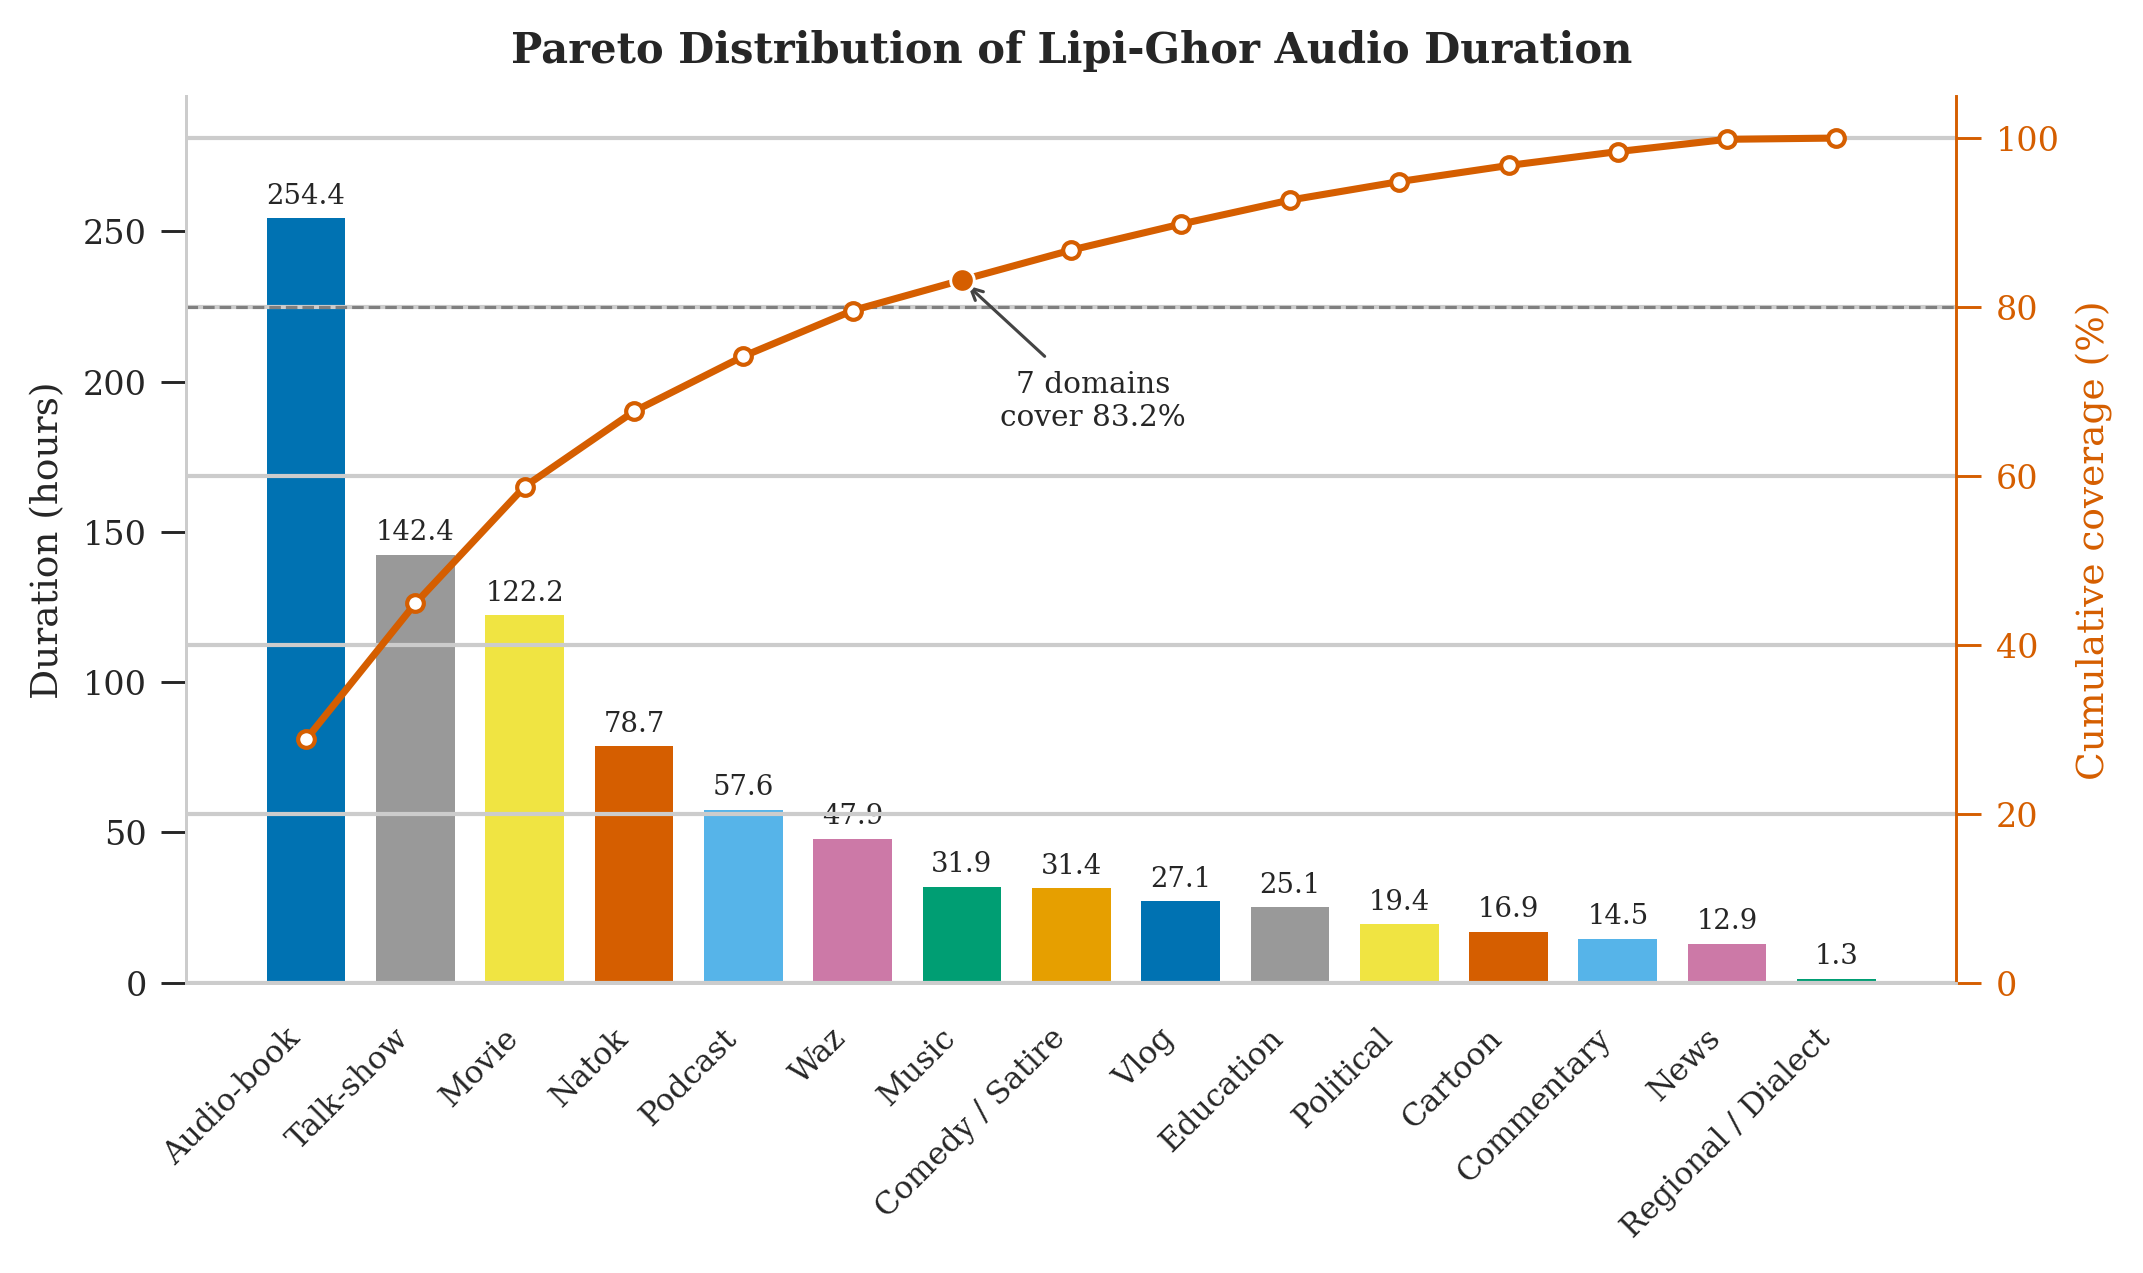
The corpus is intentionally multi-domain but naturally imbalanced: long, caption-rich sources such as audiobooks and talkshows contribute more hours, while regional, health and service content remain much smaller. This reflects the availability of Bengali captions in the wild rather than an artificially balanced benchmark.
| Corpus | Hours | Domains | Diarized | Long-form |
|---|---|---|---|---|
| Common Voice bn | ~40 | 1 | — | — |
| BengaliAI Speech | ~1200* | few | — | — |
| OOD-Speech (test) | 23 | 17 | — | — |
| BengaliLoop (eval) | small | few | ✓ | ✓ |
| Lipi-Ghor | 885 | 17 | ✓ | ✓ |
* Predominantly short, read or controlled speech.
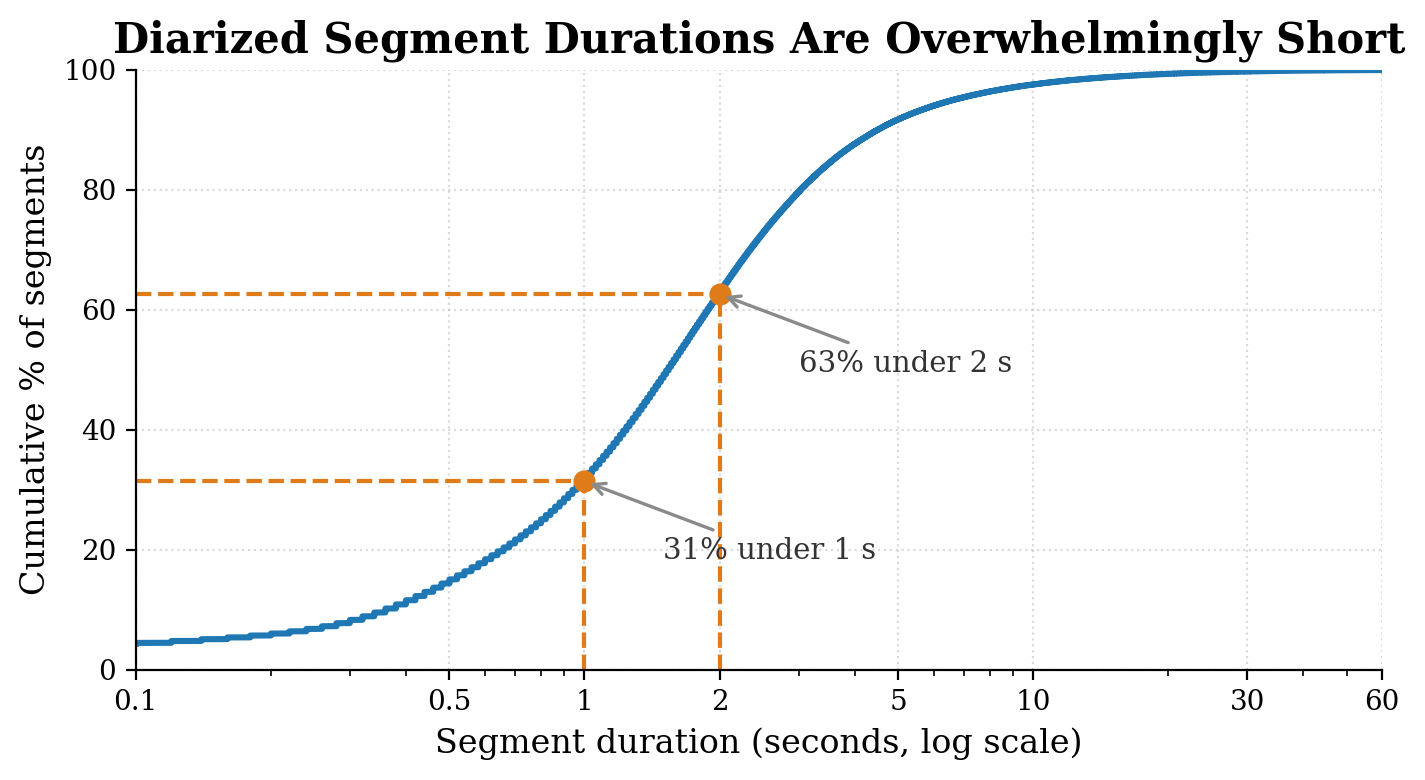
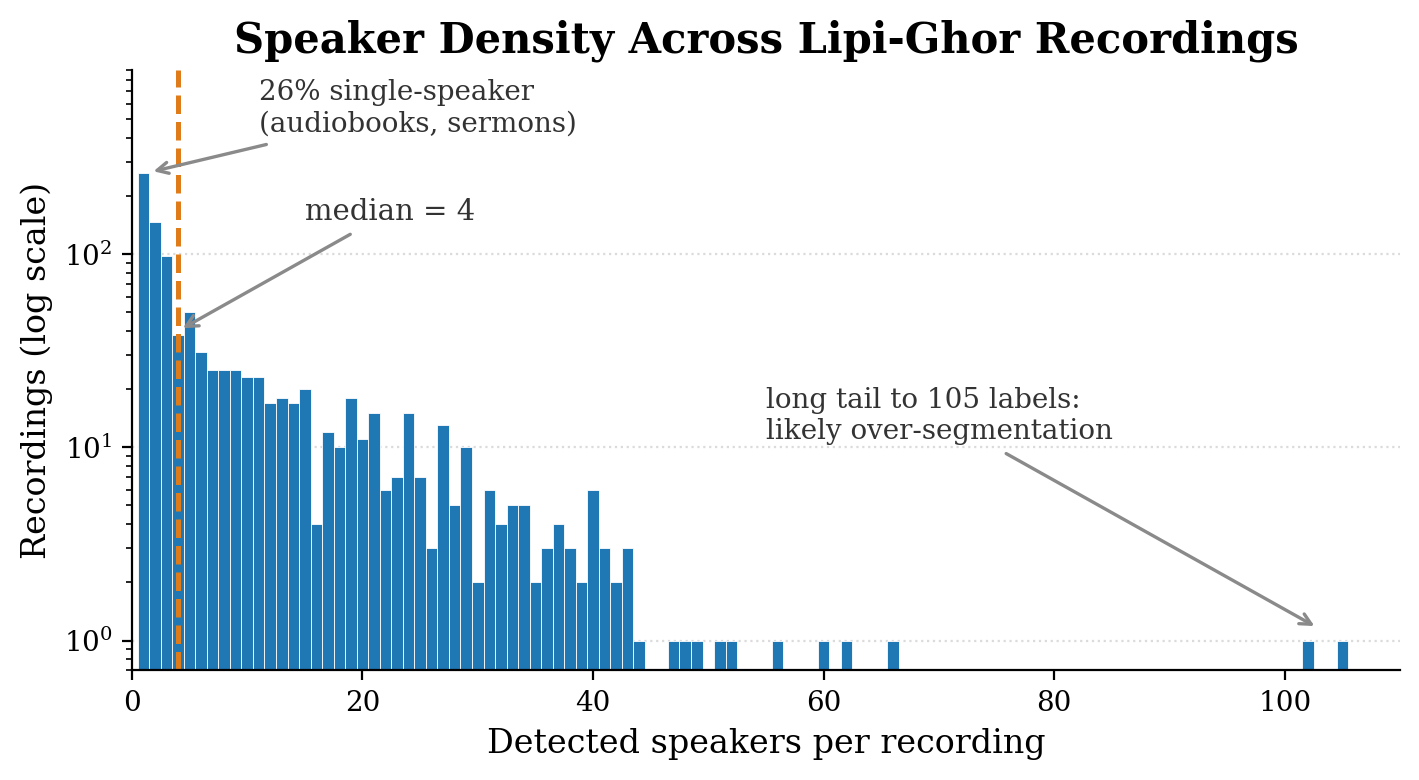
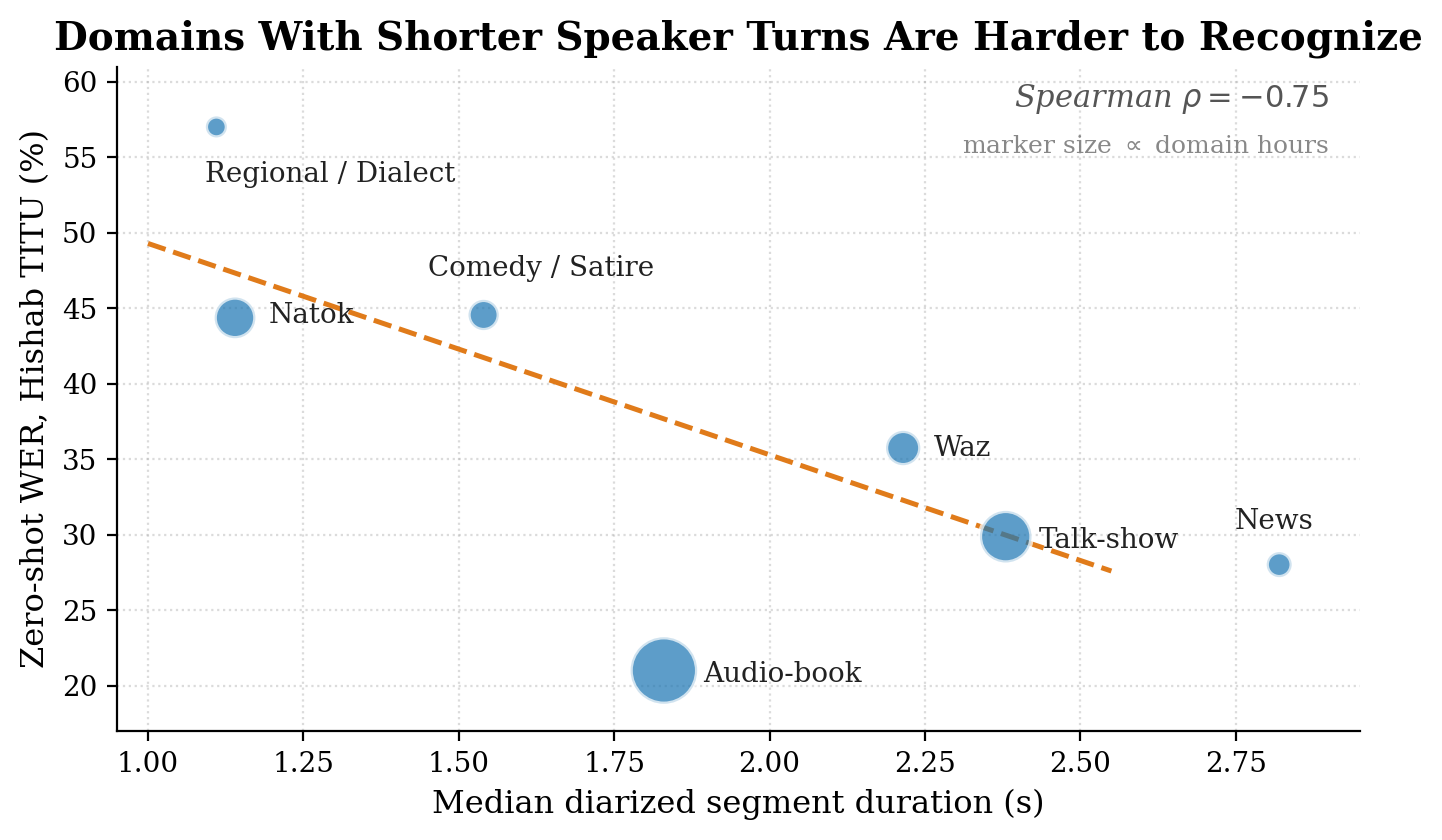
Lipi-Ghor contains 984,647 speaker-attributed segments. The median recording contains four detected speakers, while the median segment duration is 1.54 seconds. These statistics expose the turn-taking structure that is invisible in conventional sentence-level Bengali ASR corpora.
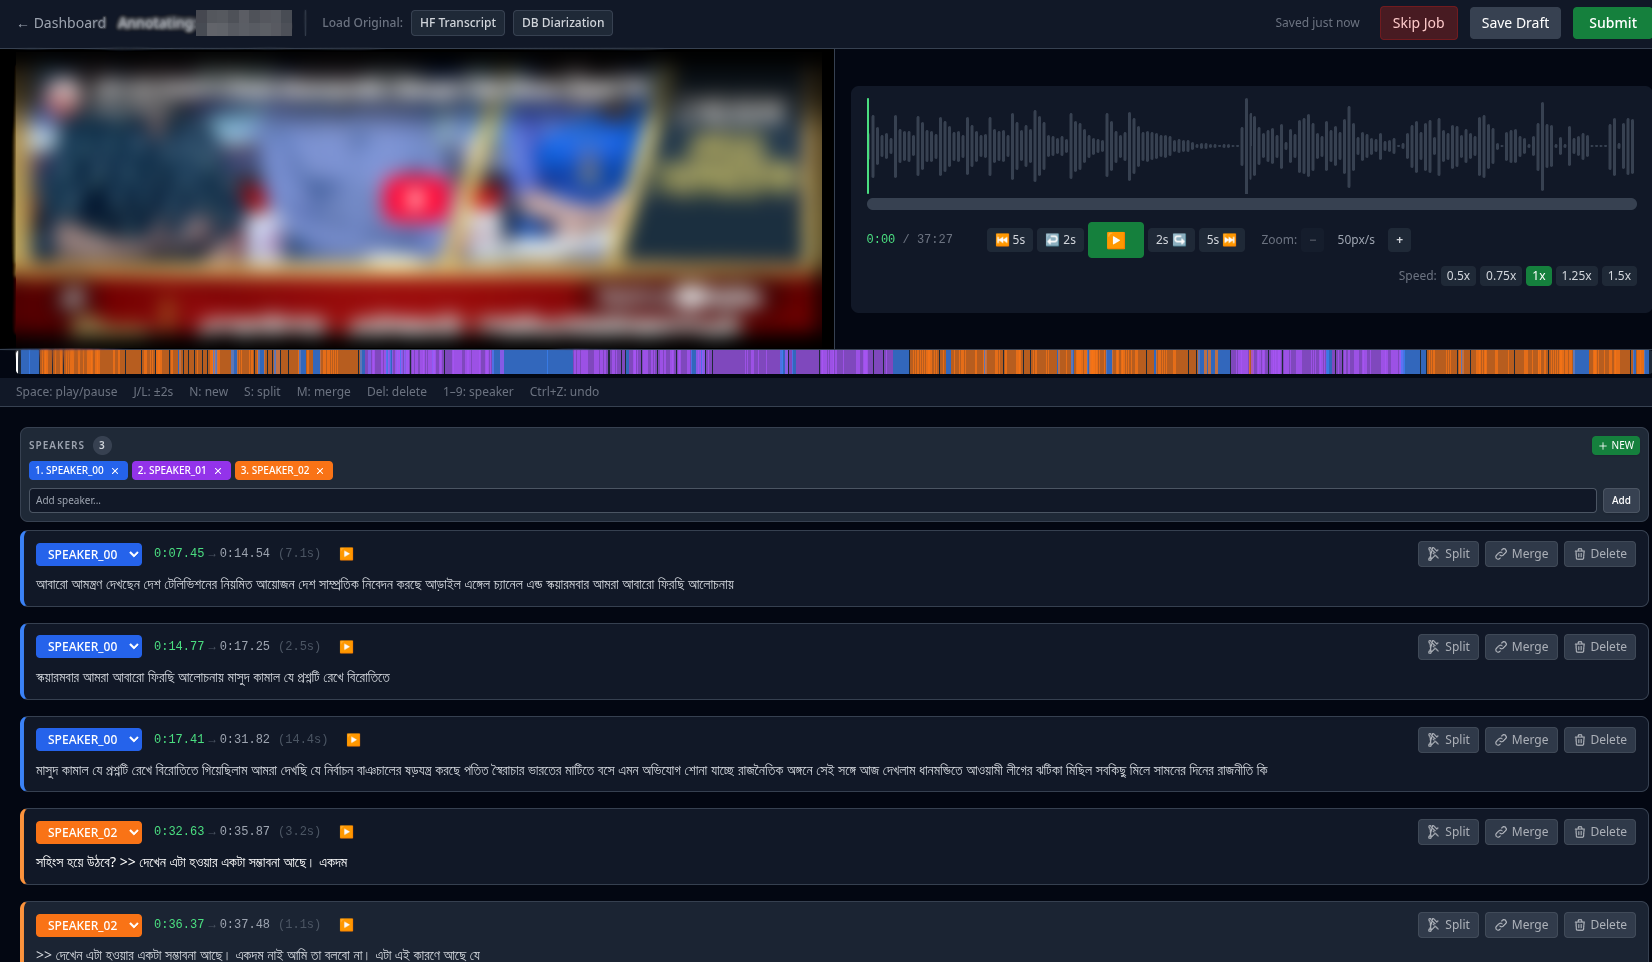
The gold split contains 500 clips sampled across all 17 domains. Seventeen native Bengali-speaking volunteers contributed approximately 30 hours of correction work, reviewing both transcript content and speaker attribution.
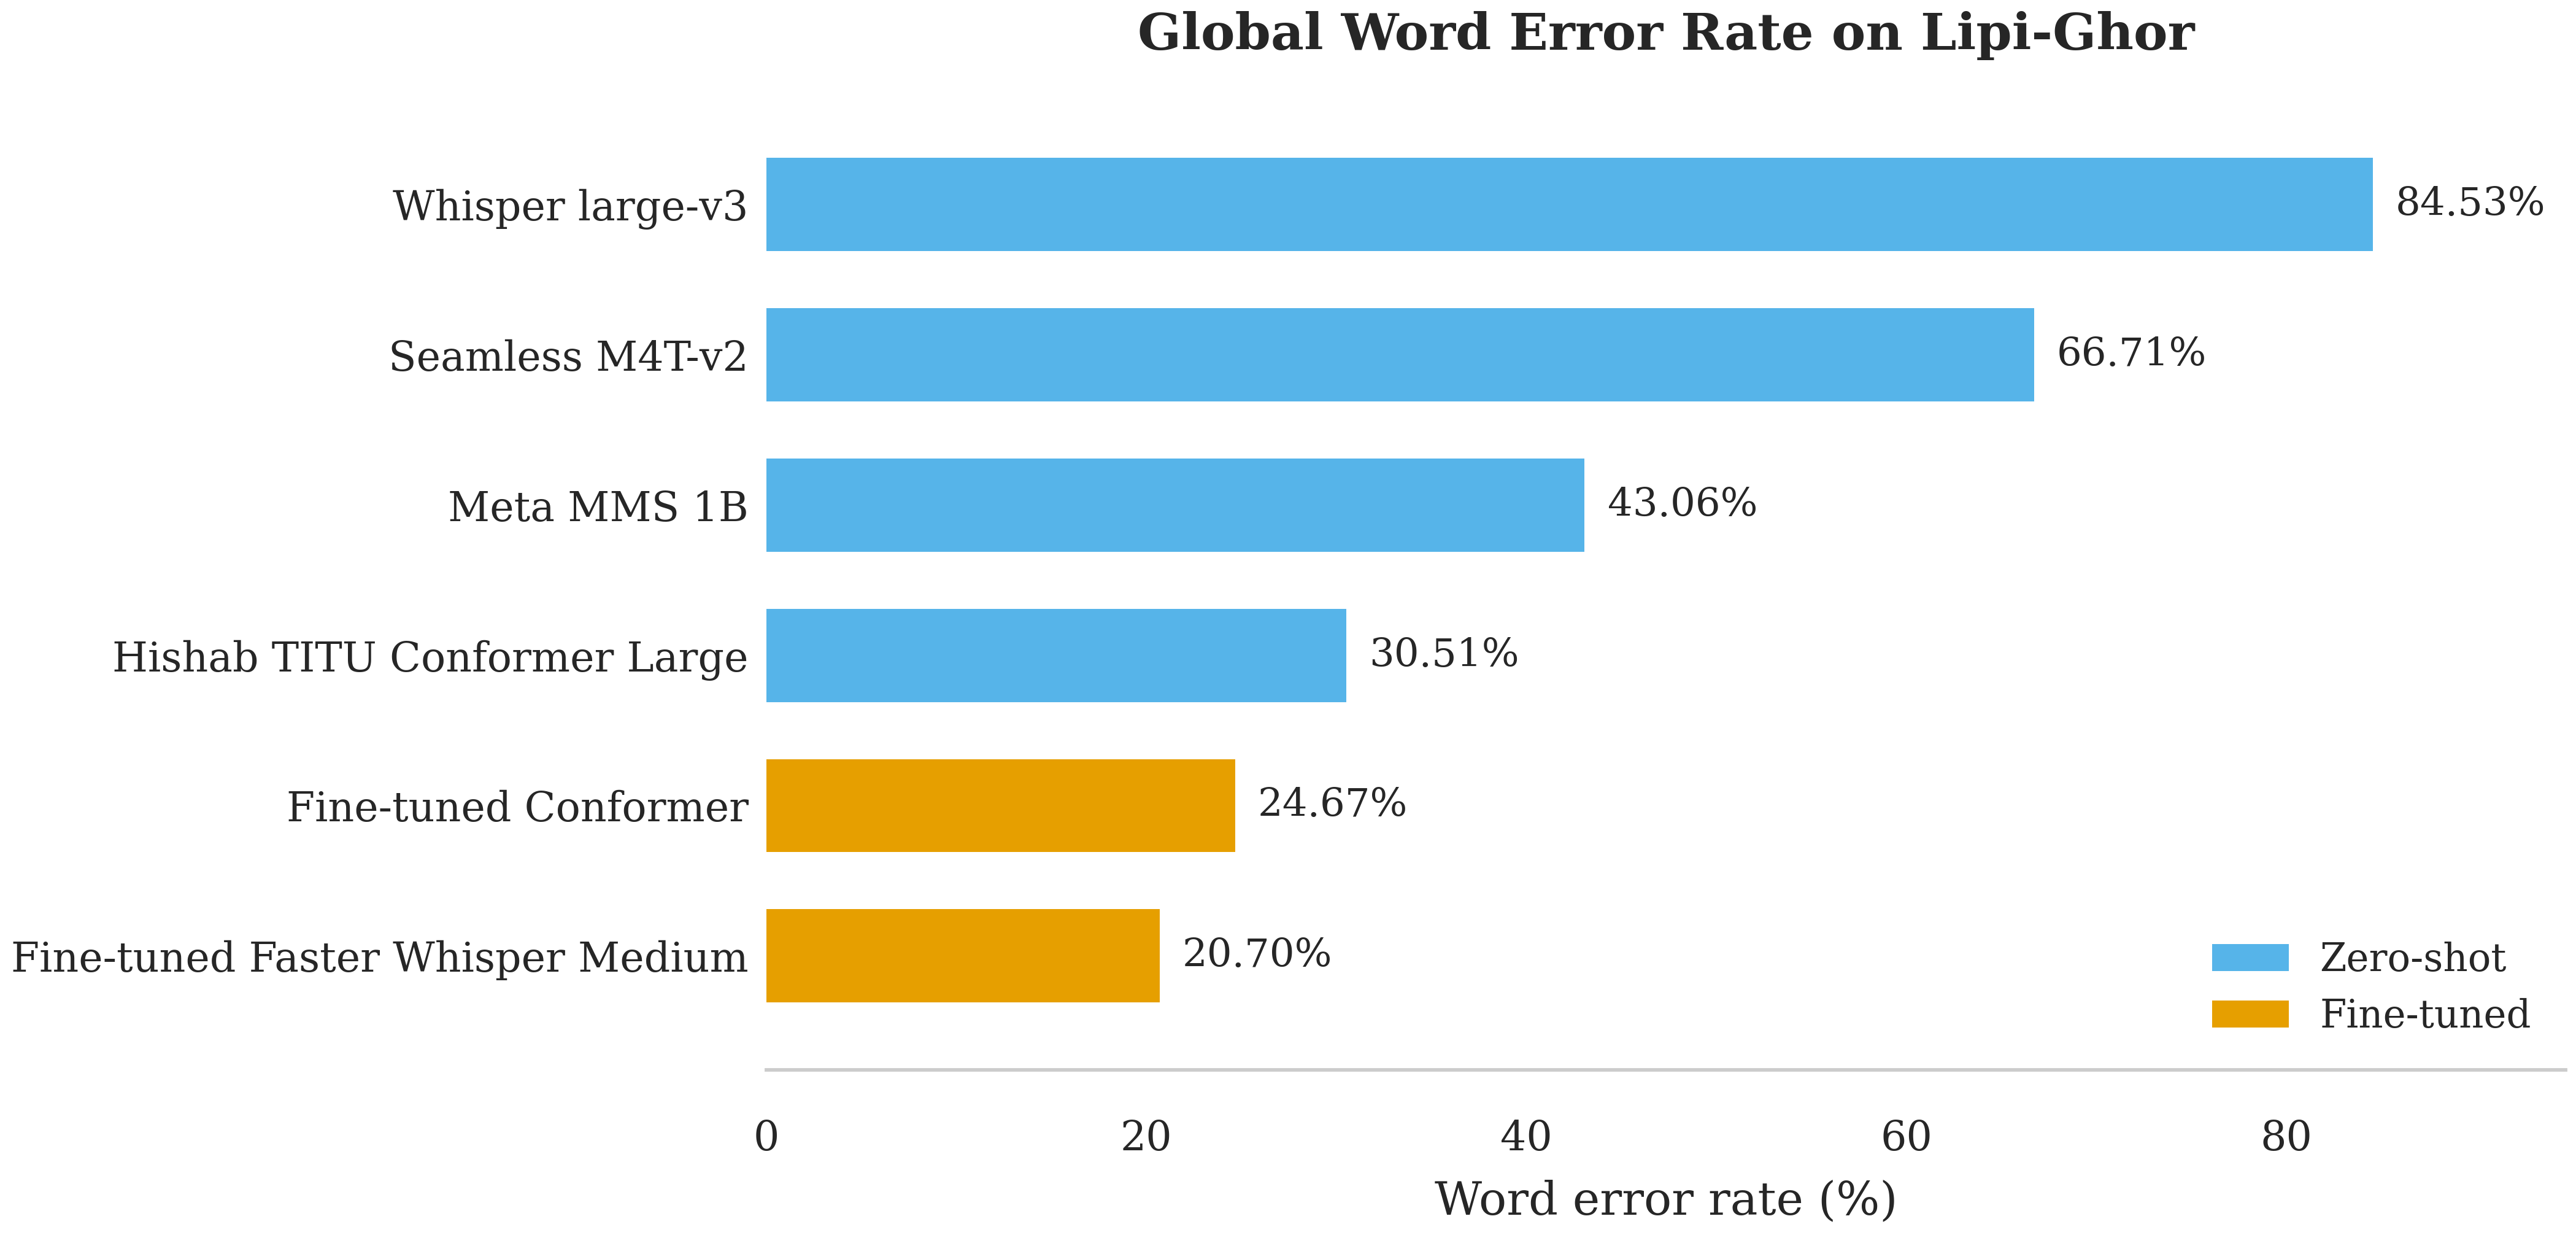
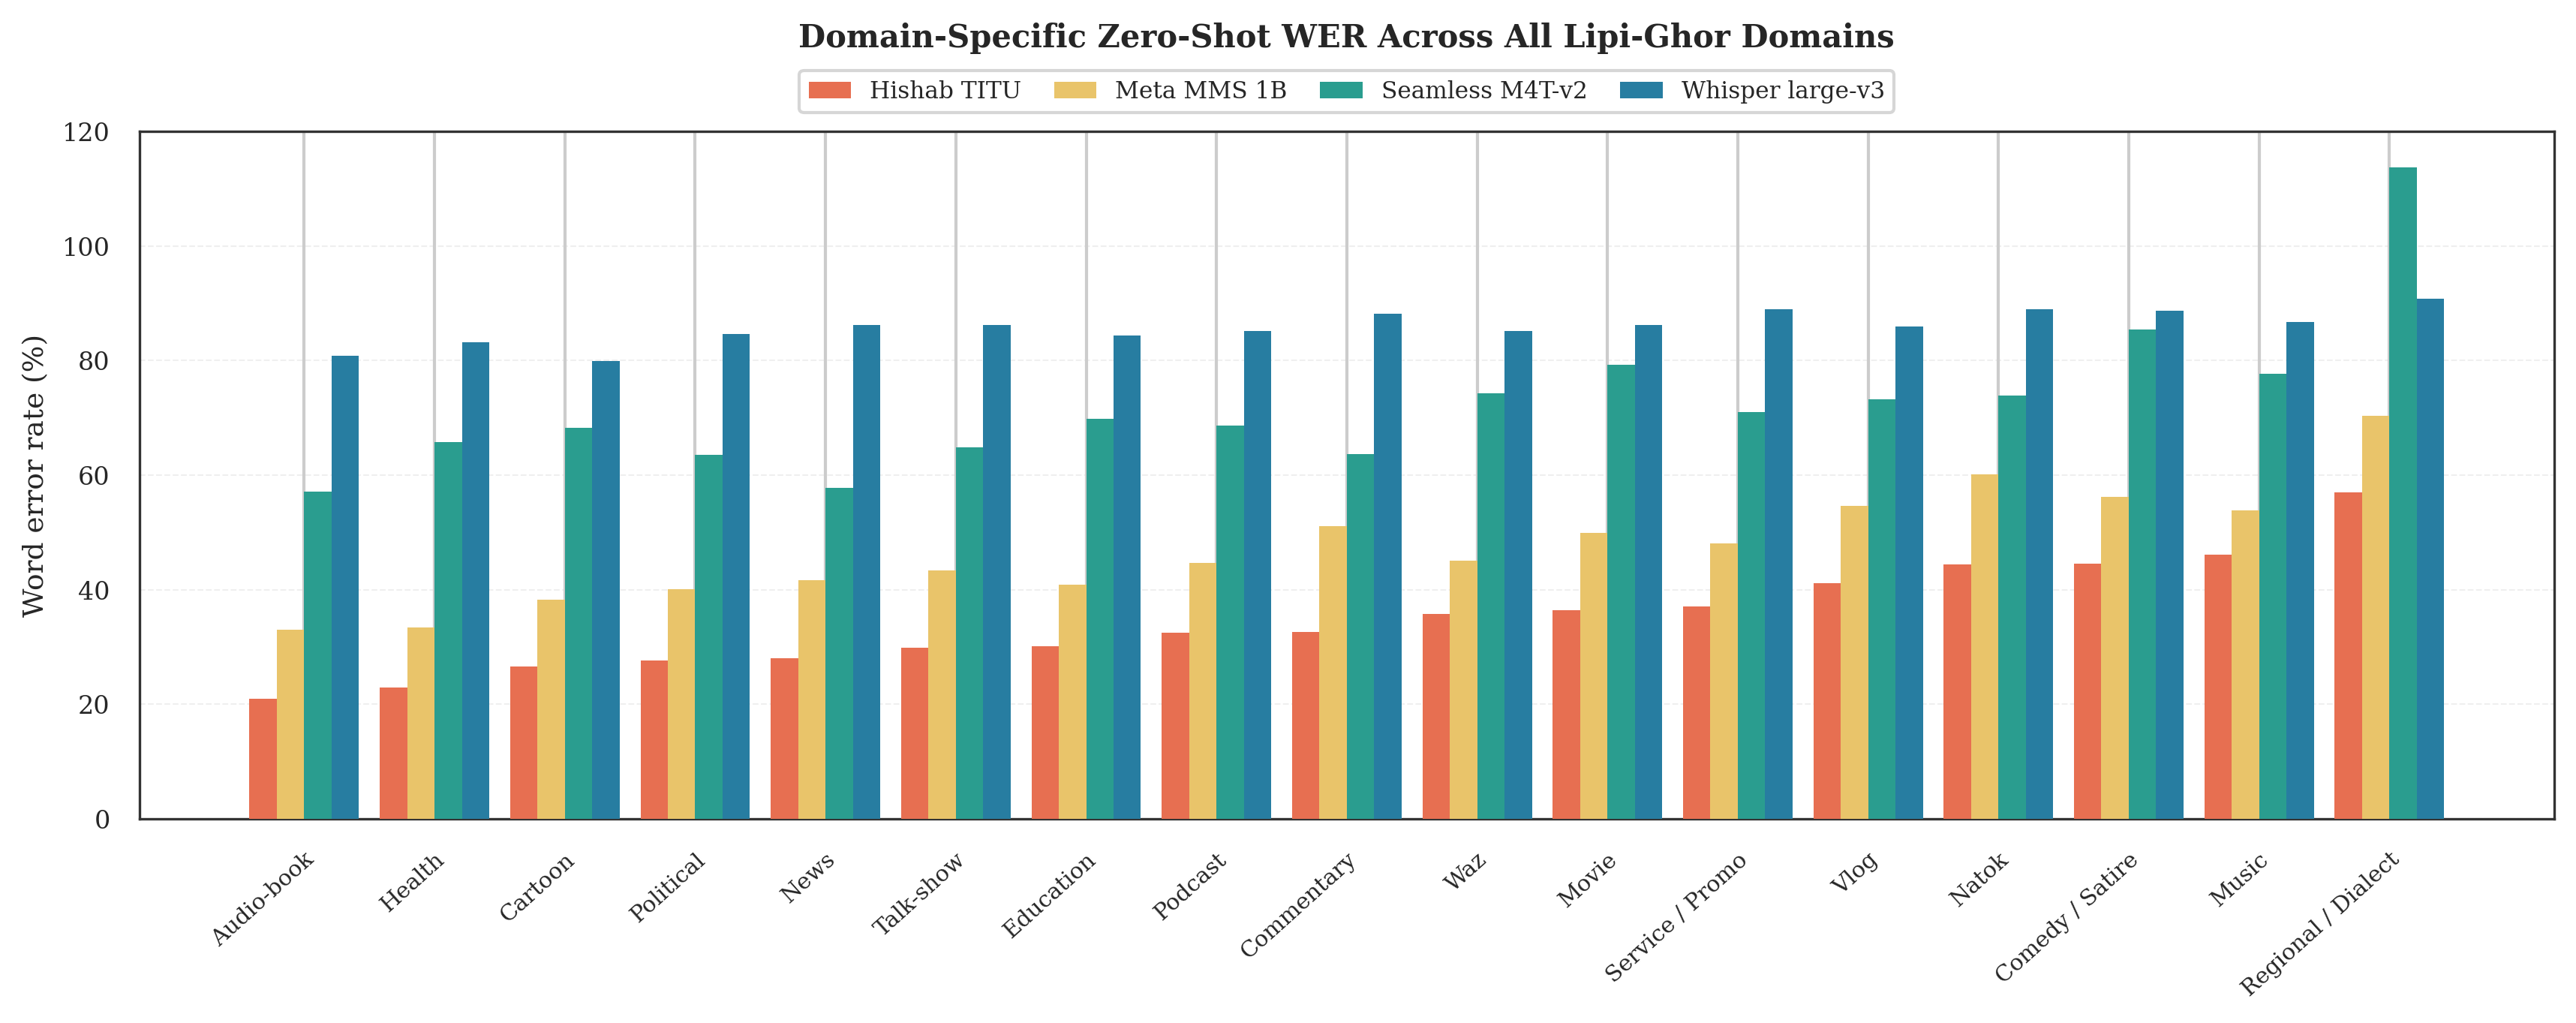
Four widely used systems are evaluated in zero-shot conditions, and two models are fine-tuned using Lipi-Ghor data. Fine-tuned Faster Whisper Medium reaches 20.70% WER, while the results consistently show larger degradation on emotive, dialectal and structurally difficult speech.
| Model | WER | CER |
|---|---|---|
| Hishab TITU Conformer-L | 30.51 | 18.23 |
| Meta MMS 1B | 43.06 | 21.16 |
| Seamless M4T-v2 | 66.71 | 45.54 |
| Whisper large-v3 | 84.53 | 72.92 |
| Model | WER | CER |
|---|---|---|
| Fast Conformer (A) | 24.67 | 15.56 |
| Faster Whisper Medium (B) | 20.70 | 11.90 |
| Moonshine-Base Bengali† | 21.54 | 10.79 |
Caption-derived transcripts are not fully human-verified and can differ from human references in punctuation, normalization and code-switched speech.
Bulk speaker labels are automatically generated and should be treated as corpus metadata, not as a completely human-validated diarization benchmark.
Raw audio is not redistributed. Original contributions are released under CC-BY-4.0; caption-derived transcripts remain subject to source rights and research-use constraints.
@dataset{lipighor2026,
  title     = {Lipi-Ghor: A Large-Scale Bengali Speech Dataset with Speaker Diarization and Transcription},
  author    = {Hasan, Sanjid and Fuad, A. H. M. and Labib, Risalat and Hasan, Bayazid},
  year      = {2026},
  publisher = {Hugging Face},
  doi       = {10.57967/hf/7877},
  url       = {https://huggingface.co/datasets/Sanjidh090/Lipi-Ghor-bn-882-SSTT}
}